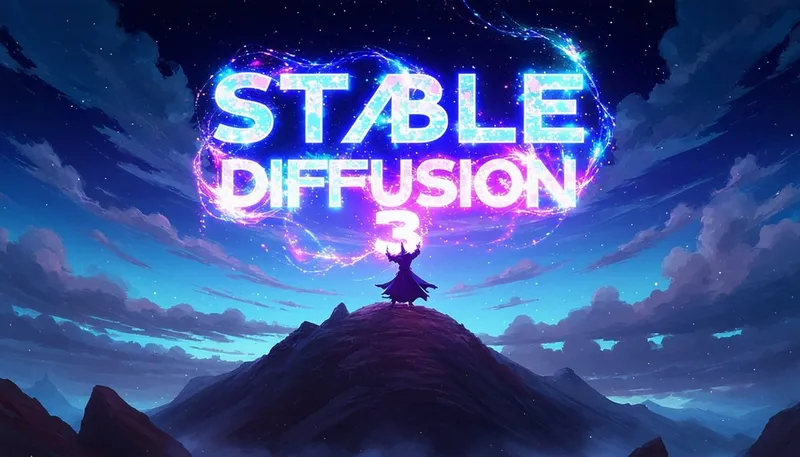
Announcing Stable Diffusion 3, our most capable text-to-image model, utilizing a diffusion transformer architecture for greatly improved performance in multi-subject prompts, image quality, and spelling abilities. Today, we are opening the waitlist for early preview. This phase is crucial for gathering insights to improve its performance and safety ahead of open release. You can sign up to join the waitlist and learn more here: t.co/lX8z1UTc8s #stablediffusion3 Prompt: Epic anime artwork of a wizard atop a mountain at night casting a cosmic spell into the dark sky that says "Stable Diffusion 3" made out of colorful energy
- Views
- 1,443,983
- Likes
- 4,906
- Replies
- 222
- Reposts
- 1,212
- Quotes
- 445
- Bookmarks
- 892
Announcing Stable Diffusion 3, our most capable text-to-image model, utilizing a diffusion transformer architecture…
The post announces Stable Diffusion 3 as a new text-to-image model with stronger multi-subject prompting, image quality, and spelling. Its fantasy artwork shows a wizard-like figure projecting the model name into a colorful night sky, while the caption invites people to join the early-preview waitlist.
- Views
- 1.4M
- Likes
- 4.9K
- Replies
- 222
- Reposts
- 1.2K
- Quotes
- 445
- Bookmarks
- 892
- Topics
Analysis
The post announces Stable Diffusion 3 as a new text-to-image model with stronger multi-subject prompting, image quality, and spelling. Its fantasy artwork shows a wizard-like figure projecting the model name into a colorful night sky, while the caption invites people to join the early-preview waitlist.
Sign in to see the full analysis.
Sign inAnnouncing Stable Diffusion 3, our most capable text-to-image model, utilizing a diffusion transformer architecture for greatly improved performance in multi-subject prompts, image quality, and spelling abilities. Today, we are opening the waitlist for early preview. This phase is crucial for gathering insights to improve its performance and safety ahead of open release. You can sign up to join the waitlist and learn more here: https://t.co/lX8z1UTc8s #stablediffusion3 Prompt: Epic anime artwork of a wizard atop a mountain at night casting a cosmic spell into the dark sky that says "Stable Diffusion 3" made out of colorful energy
Announcing Stable Diffusion 3, our most capable text-to-image model, utilizing a diffusion transformer architecture for greatly improved performance in multi-subject prompts, image quality, and spelling abilities.
- 01The Announcement
Announcing Stable Diffusion 3, our most capable text-to-image model, utilizing a diffusion transformer architecture for greatly improved performance in multi-subject prompts, image quality, and spelling abilities.
- 02The Early Access Setup
Today, we are opening the waitlist for early preview. This phase is crucial for gathering insights to improve its performance and safety ahead of open release.
- 03The Call to Action
You can sign up to join the waitlist and learn more here: https://t.co/lX8z1UTc8s #stablediffusion3 Prompt: Epic anime artwork of a wizard atop a mountain at night casting a cosmic spell into the dark sky that says "Stable Diffusion 3" made out of colorful energy
Reusable caption template.