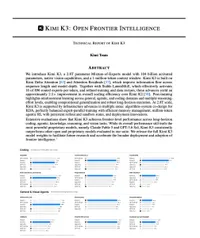
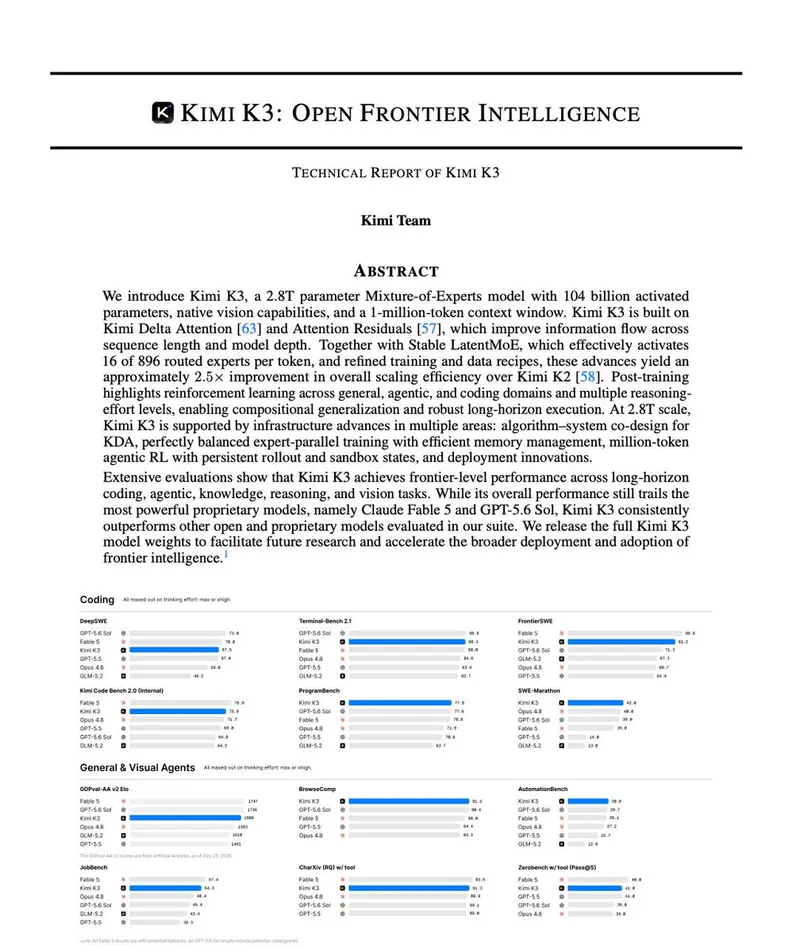
Releasing the model weights and technical report of Kimi K3. Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window. New model architecture: 2.5x the intelligence per unit of compute, not just more params. Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale. Model weights: t.co/7m7eEg6Y0B Tech report: t.co/yeu6cjpMCT Tech blog: t.co/YTfiMSNM1f
- Views
- 14,623,733
- Likes
- 45,900
- Replies
- 1,531
- Reposts
- 7,199
- Quotes
- 2,338
- Bookmarks
- 14,111
Releasing the model weights and technical report of Kimi K3.
The post announces the release of Kimi K3 model weights and its technical report. The attached report page highlights the model’s architecture, long context window, visual understanding, efficiency claims, and benchmark results.
- Views
- 14.6M
- Likes
- 45.9K
- Replies
- 1.5K
- Reposts
- 7.2K
- Quotes
- 2.3K
- Bookmarks
- 14.1K
- Topics
Analysis
The post announces the release of Kimi K3 model weights and its technical report. The attached report page highlights the model’s architecture, long context window, visual understanding, efficiency claims, and benchmark results.
Sign in to see the full analysis.
Sign inReleasing the model weights and technical report of Kimi K3. Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window. New model architecture: 2.5x the intelligence per unit of compute, not just more params. Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale. Model weights: https://t.co/7m7eEg6Y0B Tech report: https://t.co/yeu6cjpMCT Tech blog: https://t.co/YTfiMSNM1f
Releasing the model weights and technical report of Kimi K3.
- 01The Announcement
Releasing the model weights and technical report of Kimi K3.
- 02The Capability Case
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window. New model architecture: 2.5x the intelligence per unit of compute, not just more params.
- 03The Expanded Access
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale. Model weights: https://t.co/7m7eEg6Y0B Tech report: https://t.co/yeu6cjpMCT Tech blog: https://t.co/YTfiMSNM1f
Reusable caption template.